
A neural network never sees the world quite the way humans do.
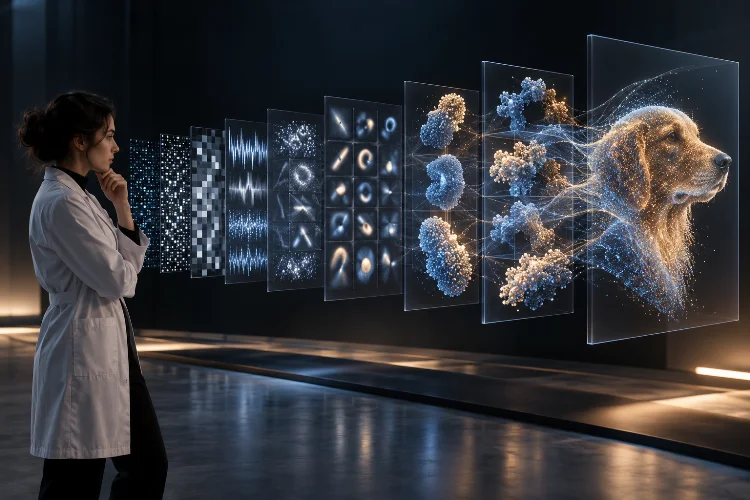
Give it a photograph of a dog and, initially, it does not see fur, ears, paws, or even a dog. It receives arrays of numerical values. Feed it a sentence and it does not automatically understand grammar, emotion, or meaning. Those concepts have to emerge through learning.
This is where representation learning in modern neural networks becomes important.
Instead of asking engineers to manually define every useful feature, neural networks learn internal representations directly from data. Early layers may recognize simple patterns, while deeper layers can capture increasingly abstract relationships.
This idea is fundamental to modern deep learning. Bengio, Courville, and Vincent described representation learning as the process of discovering useful representations that expose the underlying factors behind observed data.
From word embeddings and computer vision to multimodal models, representation learning helps explain why neural networks can reuse knowledge, generalize across tasks, and extract structure from enormous amounts of seemingly messy information.
What Is Representation Learning?
Traditional machine learning often depends heavily on feature engineering.
Imagine building an email spam detector. Engineers might manually create features such as the number of suspicious links, frequency of certain words, capitalization patterns, or sender reputation.
Representation learning changes this process.
Instead of specifying every useful signal manually, a model learns which features help solve the task. Raw information passes through multiple neural layers, where it is gradually transformed into internal numerical representations.
The influential review by Bengio and colleagues discusses how good representations can make important explanatory factors easier for machine-learning algorithms to identify while separating them from irrelevant variation.
This is one reason deep learning became so powerful.
The system learns both the representation and the final task instead of relying entirely on human-designed features.
Neural Networks Build Hierarchies of Features
Deep neural networks get their name partly from the number of computational layers between input and output.
These layers can learn increasingly abstract features.
In an image model, early layers might respond to edges, contrasts, or simple textures. Intermediate layers can combine those patterns into shapes or object parts. Deeper representations may capture higher-level concepts useful for recognizing entire objects.
The Deep Learning textbook by Goodfellow, Bengio, and Courville explains this idea as learning a hierarchy of concepts, where complicated concepts can be constructed from simpler ones.
The same general principle applies to language.
A neural network may begin with token-level information before learning relationships involving syntax, context, topics, or semantic meaning.
This hierachical structure is valuable because the model does not need one enormous leap from raw input to final prediction. It can progressively transform the data into representations that make the task easier.
Embeddings Turn Complex Information Into Useful Geometry
One of the most familiar forms of learned representation is the embedding.
An embedding converts an object – such as a word, image, user, product, or document – into a vector containing numerical values.
The interesting part is what happens inside that vector space.
Items with similar characteristics can end up positioned near each other. A recommendation system might learn that users with similar behavior occupy related regions of its embedding space.
A language model can learn representations where semantically connected words share geometric relationships.
Modern embeddings go beyond assigning a fixed vector to each word.
BERT, for example, introduced deeply bidirectional contextual representations. That means the representation of a word depends on the words surrounding it rather than remaining identical in every sentence.
Consider the word “bank.”
Its internal representation in “river bank” should differ from the representation in “bank account.” Contextual models can capture that distinction because meaning is derived from the surrounding sequence.
This makes the represenation far more useful for real language understanding.
Self-Supervised Learning Reduces Dependence on Labels
High-quality labeled datasets are expensive.
Millions of images can be collected relatively easily, but asking humans to carefully label every image, sentence, audio clip, or video quickly becomes costly.
Self-supervised learning provides another approach.
The model creates learning signals from the data itself instead of requiring humans to annotate every example.
BERT is a classic example. During pretraining, some input tokens are hidden and the model learns to predict them using surrounding context. This lets the system learn broad language representations from large collections of unlabeled text.
Contrastive learning uses a different strategy.
Google’s SimCLR framework trains a model so that differently augmented versions of the same image develop similar representations while unrelated images move further apart in representation space.
SimCLR achieved a 76.5% ImageNet top-1 result with a linear classifier on its self-supervised representation, matching the supervised ResNet-50 comparison reported by the researchers.
The important idea is that useful structure can emerge without traditional labels for every example.
That dramatically expands the amount of data available for learning.
Modern Models Learn Across Multiple Modalities
Representation learning becomes even more interesting when different forms of data share a common space.
Images and text, for example, look completely different at the input level. One consists of pixels while the other contains language tokens.
Yet both can refer to the same concept.
CLIP showed how visual and textual information could be trained together by learning which text descriptions correspond to particular images. OpenAI reported that this produced transferable visual representations capable of zero-shot classification across a range of datasets.
Suppose an image contains a red sports car.
The model does not simply memorize a category number for “car.” It learns relationships between visual patterns and natural-language concepts.
This shared latent space helps make multimodal AI possible.
Similar ideas now appear across systems involving text, images, audio, video, and other data sources. Instead of maintaining completely isolated internal worlds for every modality, models can learn representations that connect them.
DeepMind has also explored representation learning through diffusion models. Its SODA research used a bottleneck representation to capture semantic properties of images while supporting reconstruction and synthesis tasks.
These approaches suggest that representation learning is becoming a central bridge between different types of machine intelligence.
Good Representations Make Transfer Learning Possible
One of the biggest practical advantages of strong learned representations is reuse.
A neural network that has already learned useful visual or linguistic patterns does not always need to start from zero when encountering a new task.
This is the basis of transfer learning.
BERT demonstrated that a pretrained language representation could be adapted to multiple downstream tasks such as question answering and natural-language inference with relatively small task-specific changes.
The same principle appears in computer vision.
A model pretrained on a broad image collection may later be fine-tuned for medical imaging, manufacturing inspection, wildlife identification, or satellite analysis.
Good representations capture patterns that remain useful beyond the original training objective.
This reduces training requirements and makes advanced machine learning more accessible to organizations that do not possess massive labeled datasets.
However, transfer is not guaranteed.
Representations trained on one distribution may perform poorly when the new environment differs substantially. Strong generlization therefore requires careful evaluation rather than assuming that pretraining automatically solves every downstream problem.
Representation Quality Still Needs Careful Evaluation
A representation can look impressive mathematically while encoding the wrong information for the real task.
Consider a model trained to recognize animals.
If most training photographs of cows happen to contain green fields, the system could partially learn “grass” as a shortcut for identifying cows. Its accuracy might appear strong until it sees a cow indoors.
This illustrates why researchers evaluate representations through downstream tasks, transfer performance, robustness tests, and other probes.
SimCLR research, for example, evaluated self-supervised representations by placing a relatively simple classifier on top of the learned features.
If those representations already contain useful information, the classifier should perform well without requiring the entire network to relearn the task.
Representation quality also involves questions of bias.
A learned embedding reflects patterns in its training data, including unwanted correlations. Increasing model size does not automatically remove those dependancies.
Developers therefore need to examine what information a representation captures, what it ignores, and whether those internal patterns remain reliable when data changes.
Learning useful features is only part of the challenge. Making sure those features correspond to the right real-world concepts is equally important.
Representation learning sits at the heart of modern neural networks because it determines how raw information becomes something a model can actually use.
Deep networks gradually transform pixels, tokens, audio signals, and other inputs into increasingly meaningful internal features.
Embeddings organize those features into useful vector spaces, while self-supervised and multimodal learning allow models to discover structure from enormous datasets without relying entirely on manual labels.
Strong representations also make transfer learning possible, letting knowledge gained from one problem support another.
For anyone building or evaluating modern AI, looking only at the final prediction is no longer enough. Examine the representations underneath it.
Understanding what a model learns internally provides valuable insight into why it succeeds, where it may fail, and how its knowledge can be reused.
